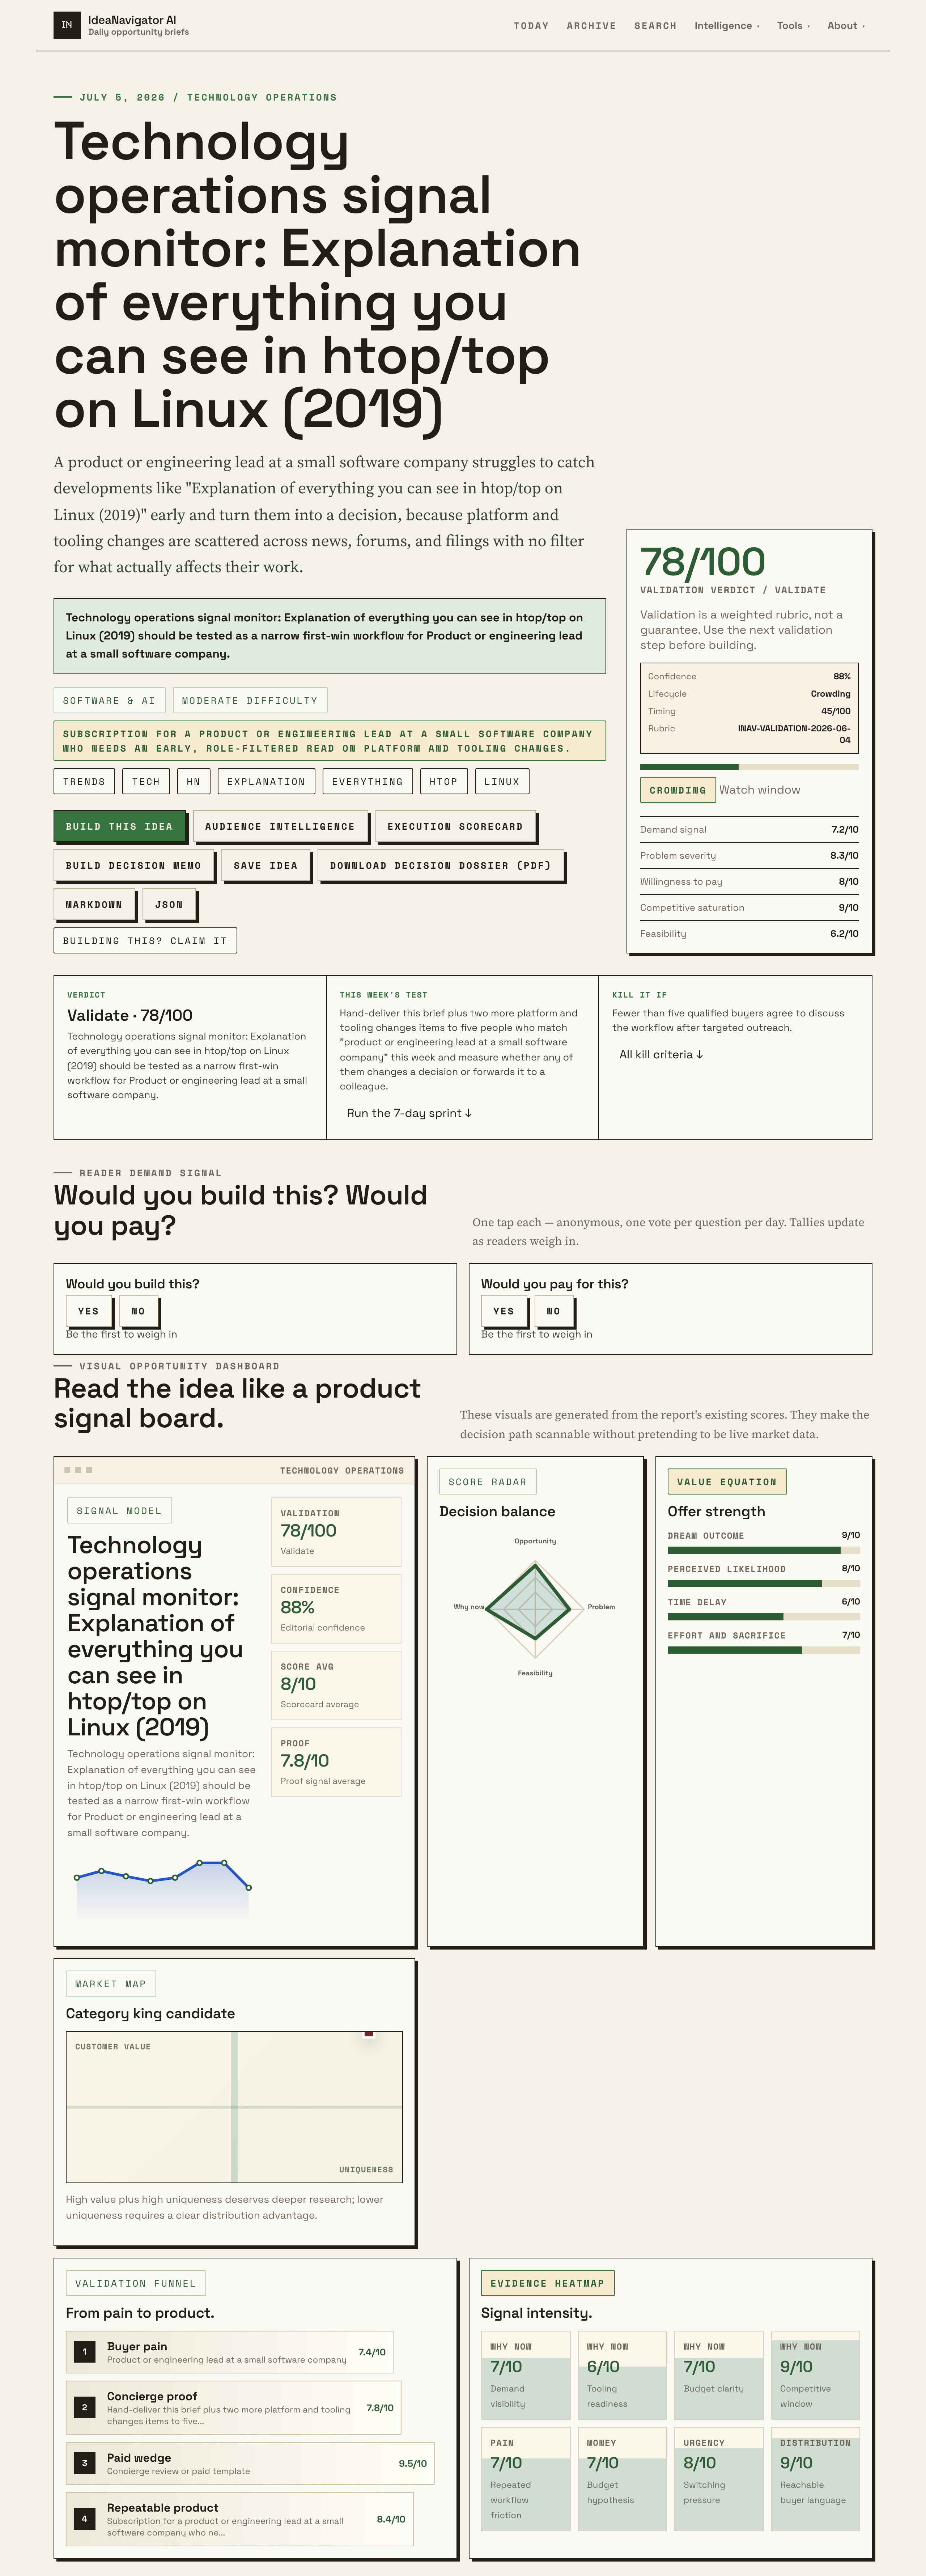
📊 Full opportunity report: Technology Operations Signal Monitor: Explanation Of Everything You Can See In Htop/top On Linux (2019) on IdeaNavigator AI — validation score, market gap, and execution plan.

Prime made for students and young adults
- Fast, free delivery for dorm and study essentials
- Prime Video and Amazon Music included
- Member-only deals
TL;DR
This article explains what information is displayed in Linux’s htop and top commands, clarifying their role in system monitoring. It highlights why understanding these tools is vital for small software company leads to respond quickly to platform changes.
Linux system administrators and developers frequently use htop and top commands to monitor system performance. This article offers a detailed explanation of what each element displayed in these tools represents, helping product and engineering leads interpret system signals quickly and accurately. For more insights into system monitoring, see the Technology Operations Signal Monitor: PeerTube.
Both htop and top are command-line utilities that display real-time system information on Linux systems. They show metrics such as CPU utilization, memory usage, process lists, and system load averages. While top is included by default in most Linux distributions, htop offers a more user-friendly, color-coded interface with additional features.
In htop, the top section displays overall system metrics, including CPU cores, memory, and swap usage. Below, a list of processes shows details like process IDs, user ownership, CPU and memory consumption, and command-line arguments. These elements help users identify resource-hungry processes and system bottlenecks.
Understanding what each column and metric means allows product and engineering leads to detect early signs of system stress or failures, enabling faster decision-making. This is similar to how Fabrice Bellard’s work influences efficient system monitoring. For instance, high CPU load or memory exhaustion can indicate underlying issues that require immediate attention or optimization.
Why Linux Monitoring Tools Matter for Small Software Teams
For small software companies, quickly interpreting system performance signals can be critical to maintaining service reliability and optimizing infrastructure costs. Knowing what each element in htop and top indicates helps leads respond proactively to platform changes, avoiding outages or degraded performance. This understanding also supports better planning for capacity and troubleshooting efforts, especially when platform updates or tooling modifications are announced.
Popular right now

Philips 3300 Series Fully Automatic Espresso Machine with LatteGo Milk System

Dreame L50 Ultra Robot Vacuum and Mop

Bose QuietComfort Wireless Bluetooth Headphones with Active Noise Cancellation, Mic, USB‑C Charging, Deep Bass, 24‑Hour Battery – White Smok
As an affiliate, we earn on qualifying purchases.
Role of htop and top in Linux System Monitoring
htop and top have been standard tools for Linux system monitoring for years, with htop introduced as a more advanced, user-friendly alternative in 2019. These tools are frequently referenced in developer forums, technical documentation, and system administration guides. The ability to quickly read and interpret their output is a core skill for technical leads managing Linux-based infrastructure.
Recent discussions on Hacker News highlighted increased interest in these tools as platform and tooling changes accelerate. Small teams rely on such real-time signals to assess the impact of updates, security patches, or configuration changes, making understanding these tools more relevant than ever.
“Knowing what each metric in htop and top represents helps us respond faster when system performance dips.”
— an anonymous system administrator
Unclear Aspects of Signal Interpretation in htop and top
While the basic metrics in htop and top are well understood, there is still some uncertainty about how best to interpret complex signals during rapid platform changes. It is not yet clear how these tools reflect underlying hardware or kernel-level adjustments during recent updates, or how to distinguish between normal fluctuations and critical issues in high-load scenarios.
Next Steps for System Monitoring and Signal Analysis
Going forward, small software teams should focus on developing standardized procedures for interpreting signals from htop and top. Training sessions, updated documentation, and real-world practice scenarios can help teams respond more effectively. Additionally, monitoring platform and tooling change feeds—like Hacker News—will enable proactive adjustments based on emerging signals and updates.
Key Questions
What are the main differences between htop and top?
htop provides a more user-friendly, color-coded interface with additional features such as process tree view and easier navigation, whereas top is simpler and included by default in most Linux distributions. Both display real-time system metrics but htop is generally preferred for its clarity and usability.
How can understanding these tools improve my response to platform changes?
By knowing what each metric indicates, leads can quickly identify early signs of system stress or failures, enabling faster decision-making and reducing downtime during platform updates or tooling modifications.
Are there best practices for interpreting signals in high-load scenarios?
Yes, best practices include monitoring baseline metrics regularly, correlating system signals with recent changes, and establishing thresholds for alerting. Training teams to recognize abnormal patterns is also critical.
Is there a recommended way to learn more about system signals in Linux?
Consult official documentation for htop and top, participate in Linux system administration courses, and follow discussions on technical forums like Hacker News and Stack Overflow to stay updated on best practices.
Source: IdeaNavigator AI