🔍 Read the full analysis: Inside AI: Following A Handwritten 7 Through A Neural Network on ThorstenMeyerAI.com

Prime made for students and young adults
- Fast, free delivery for dorm and study essentials
- Prime Video and Amazon Music included
- Member-only deals
TL;DR
A November 8, 2026, explainer from ThorstenMeyerAI.com follows a handwritten digit through a neural network and demonstrates how changing one bias can alter a small network’s behavior. It also describes an MIT CSAIL report on AI editing other models’ weights; that report is a blog post with public logs, not a peer-reviewed paper.
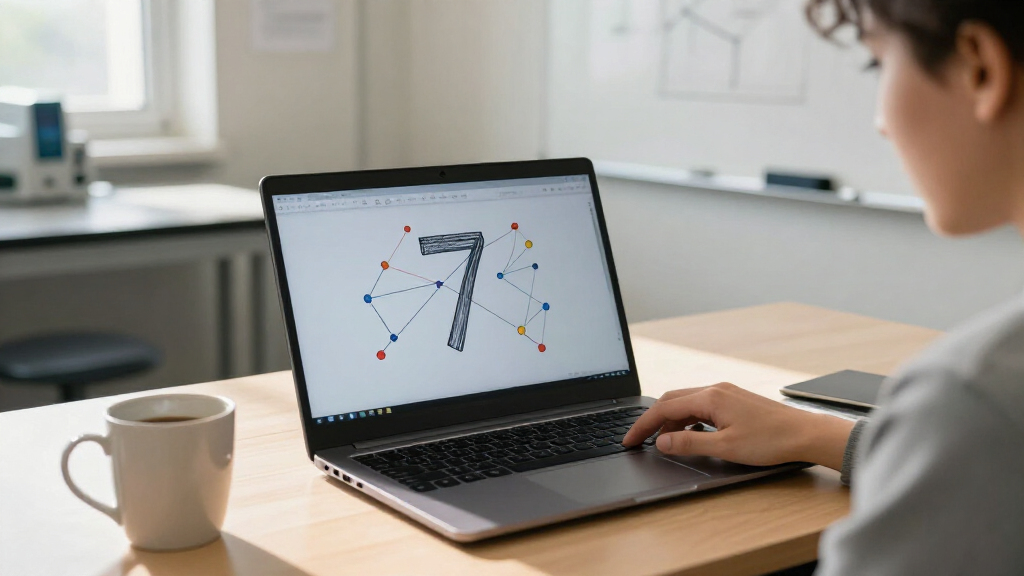
ThorstenMeyerAI.com published an explainer on November 8 tracing how a neural network can classify a handwritten seven, from pixel values through layers of arithmetic to a digit prediction. The article uses a small, hand-constructed XOR network to show how changing one bias can change its output, then connects that example to a reported MIT CSAIL demonstration in which an AI model edited another model’s weights.
The explainer describes a multilayer perceptron, a feedforward network made of dense layers. For a 28-by-28 image, the input consists of 784 pixel values. The input layer holds and passes those values along; hidden layers transform them, and the output layer can produce ten scores corresponding to the possible digits. The highest score is treated as the prediction.
At each neuron, inputs are multiplied by weights, summed with a bias and passed through an activation function. The article illustrates this with XOR, a function that returns one when two bits differ. Its hand-built network has nine numbers: weights and biases for two hidden neurons and one output neuron. Under the specified step activation, changing the output bias from −2 to −1 makes the network return one for all four possible input pairs instead of only the differing pairs.
The source says a small digit-reading network has 109,386 parameters, with about 92% in its first layer because each pixel connects to each of 128 units. It also cites an MIT CSAIL blog post reporting that an AI model read and edited other networks’ parameters. In one reported edit, 0.016% of a language model’s weights were changed and its math score rose from 7.9% to 48.1%. Those figures are claims reported in the source’s account of the blog post, not findings established here through a peer-reviewed study.
Infographic 01 · One bias, two behaviors
A network you can run by hand
Two hidden neurons check "at least one bit is on" and "at most one bit is on". The output neuron needs both. Change its bias and it needs only one.
Move the output bias from −2 to −1 and the network stops computing XOR: it returns 1 for all four inputs.
The whole network
Hidden 1: step( x₁ + x₂ − 1 )
Hidden 2: step(−x₁ − x₂ + 1 )
Output:   step( h₁ + h₂ − 2 )
step: 1 if the total is zero or greater, otherwise 0. Nine numbers in total: six in the hidden layer, three in the output neuron.
All four inputs
Hidden outputs and the final output with the original and the changed bias
| Input | At least one | At most one | Output, bias −2 | Output, bias −1 |
|---|---|---|---|---|
| 0, 0 | 0 | 1 | 0 | 1 |
| 0, 1 | 1 | 1 | 1 | 1 |
| 1, 0 | 1 | 1 | 1 | 1 |
| 1, 1 | 1 | 0 | 0 | 1 |
Sources: own arithmetic, checked with a script · the XOR example as in Goodfellow, Bengio, Courville: Deep Learning, ch. 6.
Powered by Thorsten Meyer AI
What Parameter Edits Can Change
The explainer makes a practical point about neural networks: their outputs are produced by numerical operations, and their behavior can sometimes be traced by following those operations. In the toy XOR example, a single bias has a visible, easily checked effect. That is a teaching demonstration, not evidence that a single edit in a large trained model will have an equally simple or predictable result.
The larger-model example matters because it concerns direct editing of model weights, rather than changing a prompt or retraining a system from scratch. If models can reliably identify and alter parameters that affect a target behavior, that could offer researchers another way to study or modify systems. The cited score change is a reported result from a blog post, however, and does not by itself establish how general, repeatable or safe such edits are.
Popular right now

Ninja Luxe Café Mini Espresso and Drip Coffee Machine, ES301

Ninja Luxe Café Premier 3-in-1 Espresso Machine, Drip Coffee Maker, and Cold Brew Maker

Breville Barista Express Espresso Machine with Built-In Grinder, Black Truffle
As an affiliate, we earn on qualifying purchases.
From Pixel Inputs to Model Weights
The article frames a neural network as a sequence of computations rather than an inscrutable mechanism. A dense layer can be represented as z = W x + b, followed by an activation that produces the layer’s output. That output then becomes the next layer’s input. “Hidden” refers to intermediate values, not to a claim that the calculations cannot be inspected.
The XOR example is deliberately small enough to calculate by hand. The source distinguishes architecture choices, such as width and depth, from parameters such as weights and biases, which training normally learns. In its account, researchers have also visualized image-model layers responding to simpler patterns early on and more complex features later. The source does not provide a study citation for that point, so it serves as general explanatory context rather than a new result in this report.
“A neural network is arithmetic in layers.”
— Thorsten Meyer, ThorstenMeyerAI.com
Limits of the Reported Weight Edit
The source characterizes the MIT CSAIL material as a blog post with public logs, not a peer-reviewed paper. It does not identify the model, the math evaluation, the number of trials or the conditions behind the reported score change. It is therefore unclear from the supplied material how the result was measured, whether it was independently replicated or how well it would carry over to other models and tasks.
The XOR demonstration also should not be read as a description of how a large trained network’s behavior is usually organized. In the toy case, the output bias has a straightforward effect that can be calculated exactly. The source says that in trained networks, behaviors can depend on patterns spread across many parameters and layers. The explainer does not establish that a particular neuron or weight corresponds neatly to a human-readable concept.
What Further Evidence Would Show
The source provides no announcement of a follow-up experiment or publication date for the reported weight-editing work. The next useful evidence would include the underlying methods, evaluation details and independent tests showing whether the reported effect can be reproduced across models and tasks. Until then, the numerical result remains a claim attributed to the cited MIT CSAIL blog post.
For readers following the explainer itself, its main takeaway is verifiable within the toy example: given the stated weights, biases and step activation, the output changes when the bias moves from −2 to −1. The broader question—how reliably AI systems can inspect and modify the parameters of more complex models—remains open in the material provided.
Key Questions
How does a neural network classify a handwritten seven?
In the described example, a 28-by-28 image is represented by 784 pixel values. Layers transform those values, and the output layer produces scores for the possible digits; the highest score is the prediction.
What does changing one bias do in the XOR example?
Changing the output bias from −2 to −1 makes the hand-built network return one for all four input pairs, rather than returning one only when the two bits differ.
How many parameters does the cited digit reader have?
The explainer gives a total of 109,386 parameters for its small digit-reading network and says about 92% are in the first layer. The supplied material does not give enough architecture details to independently verify that count.
Was the reported AI weight-editing result peer reviewed?
Not according to the source. It describes the MIT CSAIL material as a blog post with public logs, not a peer-reviewed paper. The methods and independent replication are not detailed in the supplied text.
Source: ThorstenMeyerAI.com